NEWVectors or files. Pick a path.Start →

    Cut SEC Filing Analysis Time by 80%

    Extract tables, charts, and XBRL data from 10-Ks, earnings calls, and investor decks-with 94% accuracy. Built for FP&A, IR, and investment teams.

    Outperforms GPT-4o, Gemini, and Claude on financial documents.

    Benchmarked: 10-K, 10-Q, earnings transcripts, investor decks, XBRL (US-GAAP + IFRS)

    Trusted by hedge funds, private equity firms, FP&A teams, and investor relations departments processing thousands of SEC filings monthly.

    Financial Document Retriever
    mixpeek.com/demo
    1
    2
    3

    Interactive retriever playground

    Launch Full Retriever

    Multimodal Extraction

    Tables, text, footnotes, charts, and XBRL with high structural accuracy.

    Numerical Reasoning

    Correct YoY, QoQ, CAGR, margins, and multi-step calculations.

    Multi-Hop Retrieval

    Answer complex analyst-grade questions in seconds.

    See It In Action

    From messy SEC filing to structured, queryable data in seconds.

    Before: Raw 10-K Filing

    // Embedded table in PDF...

    Revenue$394,328$365,817
    Cost of sales$223,546$212,981
    Gross margin??????

    // Headers span multiple rows, units unclear, no context...

    After: Structured JSON
    {
      "company": "Apple Inc.",
      "filing": "10-K",
      "fiscal_year": 2024,
      "metrics": {
        "revenue": {
          "value": 394328000000,
          "unit": "USD",
          "period": "FY2024",
          "source": "p.42, table 2, row 1",
          "xbrl_tag": "us-gaap:Revenues"
        },
        "gross_margin": {
          "value": 0.433,
          "calculated": true,
          "formula": "(revenue - cost_of_sales) / revenue",
          "verified": true
        }
      }
    }
    100%
    Source attribution
    XBRL
    Tag mapping
    Verified
    Calculations
    JSON
    API-ready output

    Capability Benchmarks

    Tested on 7 financial documents. These benchmarks measure specific capabilities, not general intelligence.

    Table Extraction

    94.2%
    Cell Accuracy

    Cell-level accuracy extracting structured data from complex financial tables with multi-level headers and merged cells.

    Mixpeek94.2%
    GPT-4 Vision78.4%
    Google Doc AI86.1%
    98.1% header detection
    91.3% merged cell handling
    Source attribution to exact cell

    Numerical Reasoning

    96.3%
    Calculation Accuracy

    Accuracy on multi-step financial calculations: YoY/QoQ growth, ratios, margins, and compound operations.

    Mixpeek96.3%
    GPT-4 Turbo62.7%
    Claude 3.568.9%
    Code execution, not estimation
    Exact numbers from XBRL
    Verifiable calculation steps

    Retrieval Precision@3

    94%
    Top-3 Accuracy

    Percentage of queries where the correct answer appears in the top 3 retrieved chunks across 1,209 document chunks.

    Mixpeek (Hybrid)94%
    Vector Only81%
    BM25 Only73%
    7 specialized embeddings
    Hybrid vector + keyword search
    Financial-domain fine-tuning

    These benchmarks test specific financial document capabilities. GPT-4 is a better general assistant-we're a better financial document parser. Different tools for different jobs.

    How It Works

    Two pipelines working together to transform documents into answers

    Extraction Pipeline
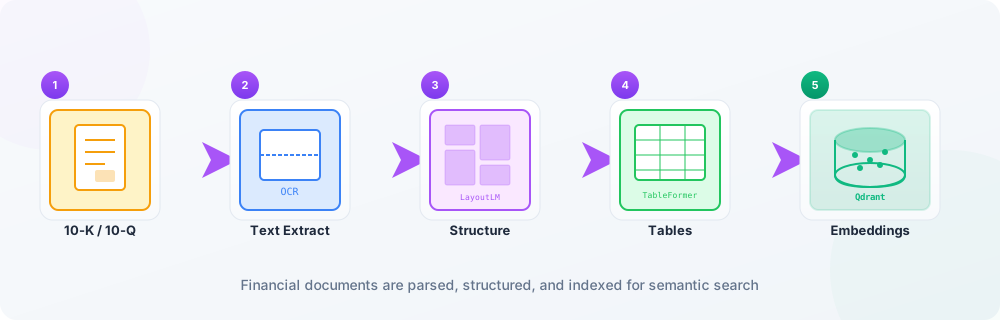
    Financial Document Extraction Pipeline - Documents are parsed, structured, and indexed

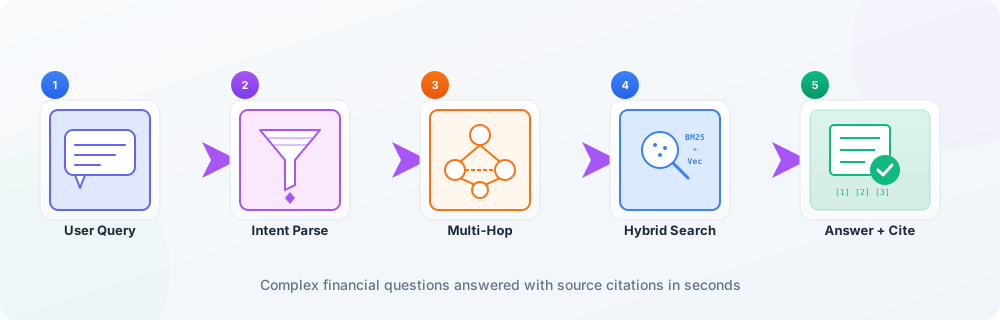
    Retrieval Pipeline

    Financial Document Retrieval Pipeline - Questions answered with citations

    Why Generic LLMs Fail at SEC Filings

    GPT-4, Claude, and Gemini are great general assistants-but financial documents need specialized extraction.

    ProblemGeneric LLMsMixpeek
    Hallucinated numbers
    Estimates and guesses financial figures
    Zero hallucination-extracted directly from XBRL facts
    Broken table parsing
    Loses row/column relationships in complex tables
    94.2% cell-level accuracy with source attribution
    Invisible charts
    Can't extract data from visual charts and graphs
    OCR + chart parsing extracts underlying values
    Single-doc limitation
    Can't cross-reference multiple filings
    Multi-hop retrieval across years and documents
    Audit-readyTraceableComplete coverageCross-filing analysisRegulatory compliance ready

    Use Cases

    Transform how your team works with financial documents

    Q4

    Q4 Earnings Prep

    Pull YoY/QoQ trends and key quotes across all filings in one query.

    Due Diligence Automation

    Compare revenue quality, margins, and debt covenants across M&A targets.

    %

    FP&A Analysis

    Extract and normalize CAGR, margins, and segment breakdowns across periods.

    SEC Compliance & Audit

    Automatically extract and validate required disclosures against filing requirements.

    Portfolio Monitoring

    Track key metrics and risk factors across portfolio companies in real-time.

    Competitive Research

    Benchmark revenue growth, R&D spend, and guidance across competitors.

    90-Second Overview

    🎥

    Product Demo Video

    Coming soon

    Get notified when it's ready

    See how Mixpeek transforms financial document intelligence

    Developer Quickstart

    Get started in minutes with our simple API

    from mixpeek import Mixpeek
    
    client = Mixpeek(api_key="YOUR_API_KEY")
    
    # Index a 10-K document
    response = client.collections.finance.index(
        document_id="10k-2024-q4",
        url="https://example.com/10k.pdf"
    )
    
    # Query financial data
    results = client.collections.finance.query(
        query="What was AAPL's YoY revenue growth in FY 2024?"
    )
    pip install mixpeekornpm install @mixpeek/sdk

    Ready to Deploy

    Includes ingestion, extraction, multi-hop retrieval, and flexible deployment options.

    Flexible pricing that scales with your ingestion volume and team size. Custom enterprise plans available for high-volume processing and dedicated support.

    Frequently Asked Questions

    Common questions from FP&A, IR, and investment teams.

    How is this different from GPT-4 or Claude?
    General-purpose LLMs estimate numbers and often hallucinate financial data. Mixpeek extracts exact values directly from XBRL tags and structured tables-every number is traceable to its source. We're specialized for financial documents, not general conversation.
    What file formats do you support?
    We support 10-K/10-Q filings (HTML, XBRL), earnings call transcripts (PDF, DOCX), investor presentations (PPTX, PDF), and Excel models. Our extraction handles embedded tables, charts, footnotes, and multi-page layouts.
    How accurate are the extracted numbers?
    94.2% cell-level accuracy on financial tables and 96.3% on multi-step calculations. Every extraction includes source attribution (page, table, row/column) so your team can verify. See our benchmark report for full methodology.
    Can I self-host for compliance requirements?
    Yes. Mixpeek can be deployed on your own infrastructure (AWS, GCP, Azure, or on-prem). Your documents never leave your environment. We also offer a managed cloud option with SOC 2-ready controls.
    How does pricing work?
    We offer usage-based pricing (pay per document processed) and enterprise plans with volume commitments. Contact us for a quote based on your expected document volume.
    What's the latency for processing a 10-K?
    A typical 10-K (150-300 pages) processes in 30-60 seconds for full extraction. Retrieval queries against indexed documents return in under 500ms.
    SOC 2-ready
    Enterprise-ready
    Self-host or cloud
    API-first

    Ready to Transform Your Financial Intelligence?

    Start extracting insights from 10-Ks, earnings calls, and financial documents in minutes.

    Questions about Mixpeek for finance

    How does Mixpeek extract tables from financial documents?
    Mixpeek uses specialized models trained on financial documents to detect table structures, handle multi-level headers, and extract cell values with precise formatting. The system achieves 94.2% cell-level accuracy on complex financial tables found in 10-Ks and earnings reports, maintaining XBRL tag relationships and preserving numerical precision.
    Can Mixpeek perform financial calculations like YoY growth or margins?
    Yes, Mixpeek includes code-based numerical reasoning that can calculate YoY, QoQ, CAGR, margins, and multi-step calculations. The system generates and executes Python code to perform calculations, achieving 96.3% accuracy on financial calculation benchmarks. This ensures precise answers to analyst-grade questions.
    How accurate is information retrieval for analyst questions?
    Mixpeek achieves 94% retrieval precision@3 on multi-hop financial questions, meaning the correct answer appears in the top 3 results 94% of the time. The system uses hybrid retrieval combining semantic search with financial domain fine-tuning to understand context and relationships across multiple documents.
    Can Mixpeek process earnings call transcripts and audio?
    Yes, Mixpeek processes both earnings call transcripts and audio recordings. The system can transcribe audio, extract speaker segments, identify key topics and sentiment, and correlate spoken information with written reports. This enables comprehensive analysis across all earnings materials.
    What types of financial documents can Mixpeek analyze?
    Mixpeek processes 10-Ks, 10-Qs, 8-Ks, earnings call transcripts, investor presentations, proxy statements, annual reports, and regulatory filings. The system handles PDF, HTML, and text formats, including scanned documents with OCR. Custom document types can be added through training.
    How does Mixpeek handle XBRL data?
    Mixpeek extracts and maintains XBRL tag relationships when processing financial statements. The system can map extracted values to XBRL taxonomy tags, enabling structured queries by specific XBRL concepts and ensuring data consistency with official filings.
    Can we integrate Mixpeek with our existing financial databases?
    There is no Bloomberg, FactSet or Refinitiv connector today. Mixpeek reads from Snowflake, PostgreSQL and Supabase directly, and from S3, GCS or Azure Blob for documents and filings, which is where most firms already land vendor data. Results come back as JSON or CSV through the API for loading into a warehouse.
    How does pricing work for financial document processing?
    Pricing is based on document volume and analysis features enabled. We offer tiered pricing for small teams (10-100 documents/month) and enterprise pricing for large-scale analysis (10K+ documents). Contact us for custom pricing based on your specific requirements and volume.
    Is Mixpeek compliant with financial data security requirements?
    Mixpeek is SOC 2-ready and supports financial data security requirements. All data is encrypted in transit and at rest. We support on-premise deployment for organizations with strict data residency requirements. Access controls and audit logs are included for regulatory compliance. Mixpeek holds no SOC 2 certification and has no audit under way; the current status of each certification is published at mixpeek.com/trust.
    How does Mixpeek compare to manual analyst work?
    Mixpeek accelerates financial analysis by automating data extraction and calculation verification. Analysts using Mixpeek report 80-90% time savings on document review and data collection, allowing them to focus on interpretation and decision-making. The system handles the routine extraction while analysts focus on insights.

    Build this in the docs

    The extractors and retrieval stages this solution runs on, with API reference and worked examples.

    Run this on your own financial services content

    Point Mixpeek at the storage you already have and search your video, images, audio, and documents the way this page describes. Build starts at $25/mo for up to 1M vectors.