Filter
Search and filter documents by vector similarity using feature embeddings
stage_id feature_searchDocsView stage
Build a multi-stage search with create_retriever on the Mixpeek MCP server (https://mcp.mixpeek.com/mcp) (stages such as feature_search, attribute_filter and rerank), then query it with execute_retriever. Every MCP tool needs an API key; an agent can get one with POST https://api.mixpeek.com/v1/signup/agent.A retriever is the stable multi-stage contract an application binds to by name, so the embedding model, the index and the query plan underneath can all change without breaking a caller. That job is one layer of the semantic layer for unstructured and multimodal data, the architecture that turns raw objects into named features and serves them through contracts an application can bind to.
34 stages
Search and filter documents by vector similarity using feature embeddings
Filter documents by metadata attribute values using boolean logic
LLM-driven multi-step retrieval with iterative reasoning and tool orchestration
Generate query variations with LLM and fuse search results via RRF
Drop results below an absolute score and return no results when nothing qualifies
Rescale document scores to a common range for consistent comparison
Combine stages to build sophisticated search and retrieval pipelines. Each stage type serves a specific purpose in the data flow.
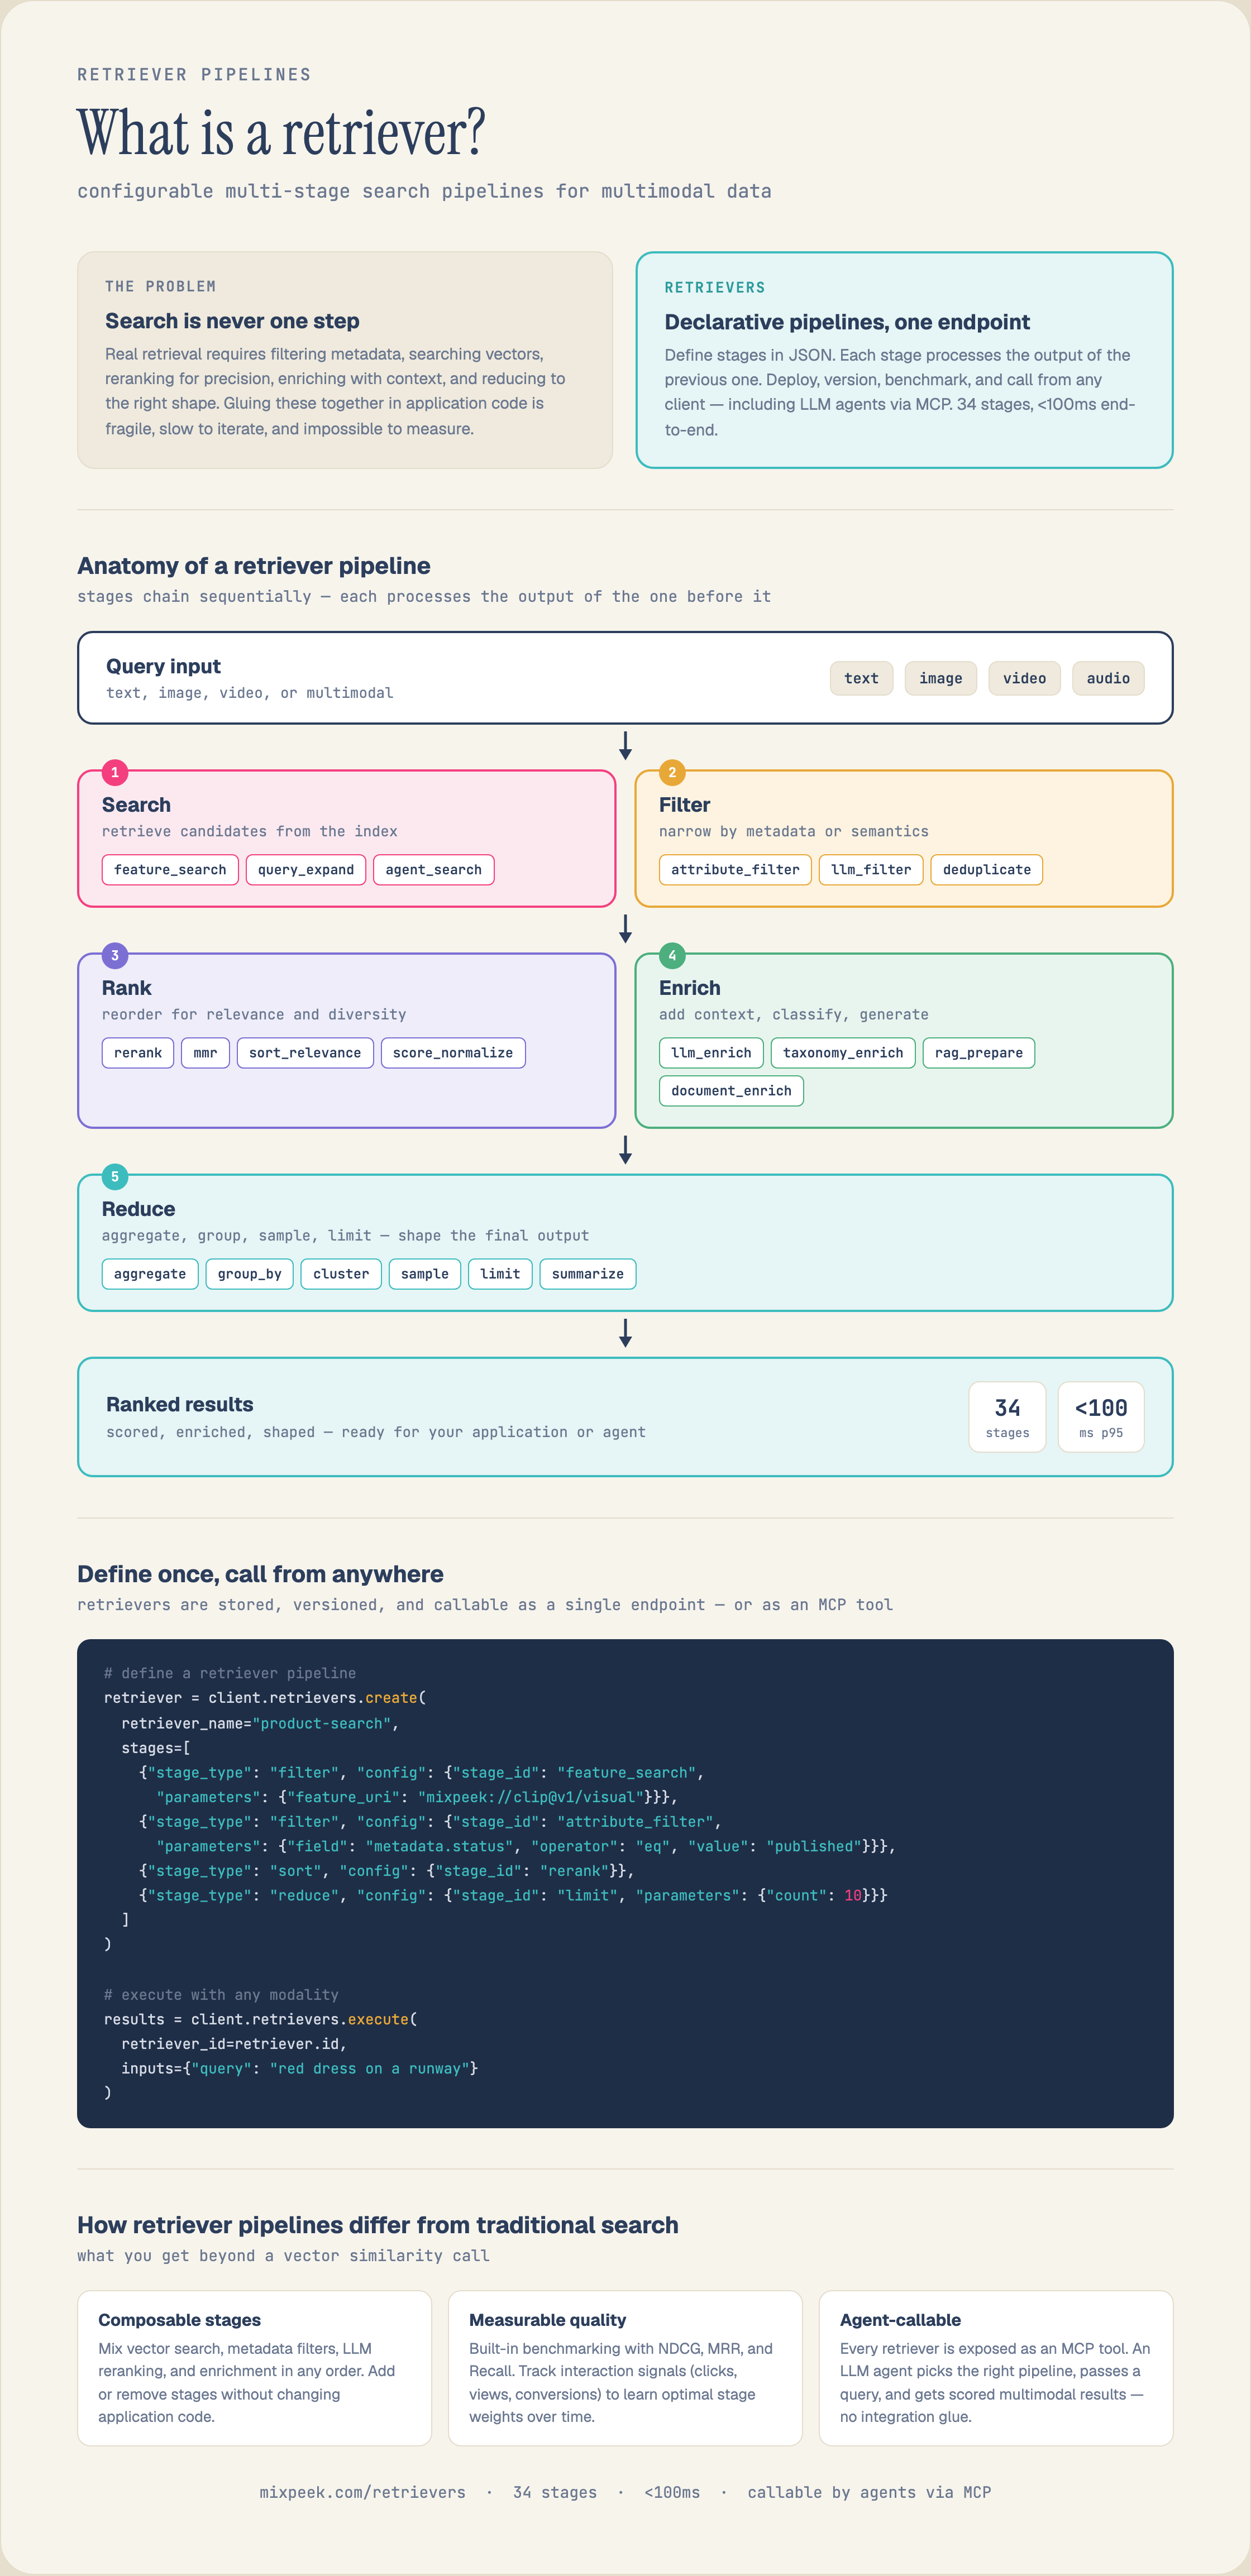
Retrieve documents from collections using semantic search, keyword search, or hybrid approaches.
Remove documents that don't match criteria using attribute filters, score thresholds, or LLM evaluation.
Reorder documents by relevance using sorting, cross-encoders, or LLM-based reranking.
Create responses from retrieved documents using RAG, summarization, or custom LLM generation.
The stages described above, with request shapes, and what each one passes to the next.