AI data curation
Find the data your model is missing. Turn model failures into training and evaluation datasets with multimodal search and sampling.
Applies empty and reads Your own samples with your model's predictions. Connect your own data before querying.
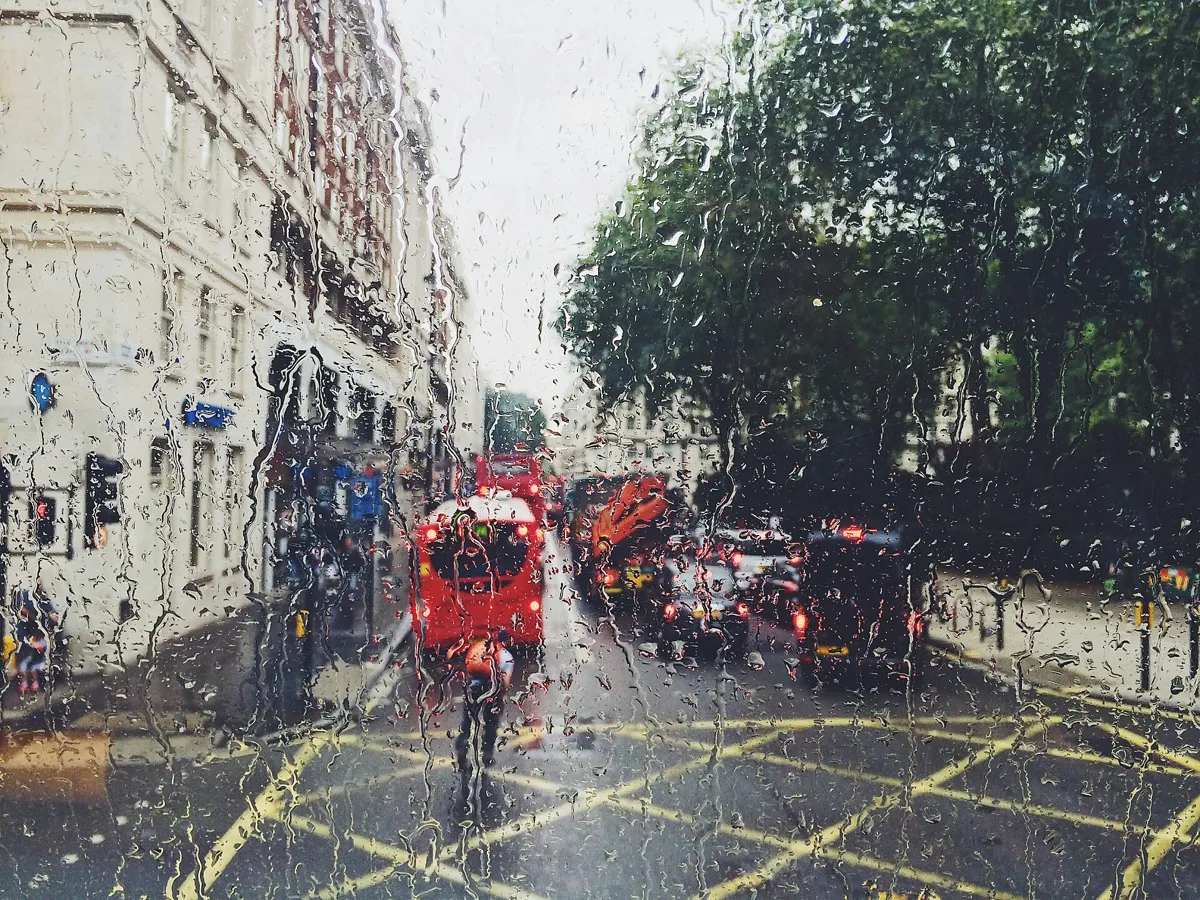 overcast sky, read as nightbrake lights in daylightreview
- samples indexed after apply
- 40 in 248 s
- night scenes in failure-discovery's top 5
- 5 of 5
- misses ranked by confidence, 0.84 down to 0.52
- 16
- day and night in the 12-sample curated pick
- 6 / 6
- click to first answer
- 68.1 s
How these were measured
- 40 in 248 s samples indexed after apply: Proof run on production, 2026-10-29: apply created the 7 resources and the seed batch in 27.5 s, and the samples collection reached 40 documents at 247.5 s.
- 5 of 5 night scenes in failure-discovery's top 5: "a dark city street at night" returned only night samples, all of them low_light misses. 23.9 s on the first, cold call.
- 16 misses ranked by confidence, 0.84 down to 0.52: hard-examples returned every wrong prediction in the seed set, most confident first, in 0.7 s. The rainy street the model called night ranks first.
- 6 / 6 day and night in the 12-sample curated pick: curate with "a city street" returned 12 results balanced across both labels, in 1.4 s. The whole proof run cost 880 credits (0.88 USD).
- 68.1 s click to first answer: from clicking apply to the first search that answers, timed on production on 7 November 2026 by the harness that runs nightly
What’s inside
- Extractors
- multimodal
- Retrievers
- failure-discovery·feature_searchsimilar-to-failure·feature_searchhard-examples·verdict_filter → sort_attributecurate·feature_search → mmr → sampleconfident-miss-monitor·verdict_filter
See it work
- a dark city street at nightfailure-discovery
on the seed set, the top 5 are all night scenes the model called day
- every sample the model got wronghard-examples
filtered on correct = false, sorted by confidence, highest first
- a city streetcurate
12 kept, near-duplicates dropped, at least 4 per label
review- samples -> hard-examples
- overcast sky, read as night
- brake lights in daylight
- route: review
How it's wired
Applies 1 buckets, 1 collections and 5 retrievers today
Drag nodes to rearrange. Drag the background to pan, ctrl or cmd plus scroll to zoom. Click a node for its settings.
What it costs
Processing is priced the way a batch is charged: each bucket's minutes, images, pages or tokens times its rate card lines. The batch dry run in Studio gives the binding quote.
Models
- Vertex AI multimodalembedding@001Provider APIEmbedding
Collections and their documents
Reads image from image
| Field | Type | Required |
|---|---|---|
| document_id | string | set by Mixpeek |
| collection_id | string | set by Mixpeek |
| label | string | no |
| prediction | string | no |
| confidence | number | no |
| correct | boolean | no |
| error_category | string | no |
| model_version | string | no |
mixpeek://multimodal_extractor@v1/vertex_multimodal_embeddingfrom Vertex AI multimodalembedding@001
Retrievers
- failure-discoveryfeature_search over samples; input query
- similar-to-failurefeature_search over samples; input query
- hard-examplesverdict_filter then sort_attribute over samples; input limit
- curatefeature_search then mmr then sample over samples; input query
- confident-miss-monitorverdict_filter over samples; input document_id
Spend limits
- Daily spend budget in the manifest
- 2 USD a day; new batches pause once it is spent
- Acceptance run ceiling
- 1.25 USD
- Model cost
- Unmeasured for 1 of 1 models
Monthly cost at your volume is in the calculator. Served models start at zero replicas, so an idle namespace runs no model.
Reward signals
The loop runs through your tools: you send samples with predictions, Mixpeek selects, your labeling tool labels the selection, your training job uses it, and the next model's predictions come back as new samples.
How reviewer decisions move the thresholds
The selection itself, recorded on each document as curation_versions with a reason, is what a release exports.
None from the template. Mixpeek records retriever executions server-side, which is telemetry about queries rather than feedback about results.
samplesmxp_retriever_executionsEach model version's predictions arrive with model_version on them, so the next round of failure-discovery runs against what the newest model still gets wrong.
Upload your samples with your model's predictions and the ground truth you have. Mixpeek finds more examples like the failures, ranks the confident misses, drops near-duplicates and balances the pick across labels, so the selection is ready for your labeling and training tools. Mixpeek finds and selects; labeling, training and scoring stay in your own tools.
- failure-discovery: describe a failure in words and get every sample that looks like it, labeled or not.
- similar-to-failure: pass the URL of an image the model got wrong and get the samples closest to it.
- hard-examples: every sample the model got wrong, most confident first, so a reviewer sees the confident misses before the ambiguous ones.
- curate: search wide, drop near-duplicates on the image vector, then sample evenly across labels: 12 kept, at least 4 per label.
- Mixpeek finds and selects. Labeling, training and model evaluation stay in your own tools, and Mixpeek does not score predictions: correctness and error categories arrive with your data.
For: AI labs, robotics and autonomous-vehicle teams, and data and evaluation vendors who know where their model fails and need more examples like the failures, picked without near-duplicates.
- samples
- One image per sample, with your own label, prediction, confidence, correct, error_category and model_version fields. Only the image is required; every field you send passes through at the path you gave it.
- samples
- One document per sample with a multimodal embedding of the image and your prediction fields carried through, so the same index answers a sentence, a photo of a failure, and a filter on correct = false.
- a dataset release
- Documented, not deployed: record the selection on each document (curation_versions), then export the collection filtered on that version as Parquet or WebDataset, with lineage and a release manifest giving every file's size and SHA-256, into your bucket.
One file spins up the namespace. Generated from the workflow above. Also served at /templates/ai-data-curation.namespace.yaml.
# ai-data-curation: one manifest spins up the namespace.
# Platform manifest schema (GET /v1/discovery/schema). Validate with POST /v1/manifest/validate,
# apply with POST /v1/manifest/apply or the Deploy button. Wiring comes from the flow diagram:
# edges are bucket -> collection sources, collection -> retriever scope, retriever -> view.
# Applying a SECOND time, over a namespace this template already created: use
# POST /v1/manifest/apply?mode=create_missing, which creates what is missing and leaves
# what exists alone. The default, create_only, fails the WHOLE apply and rolls it back if
# any resource already exists, so an upgrade looks like a dead end without this. Use
# mode=upsert to also patch resources that exist but have drifted from this file.
version: '1.0'
metadata:
  name: ai-data-curation
  description: "Namespace template ai-data-curation. Generated from the flow diagram on mixpeek.com/templates/ai-data-curation."
namespaces:
  - name: ai-data-curation
    description: "Everything below lives in this namespace."
    feature_extractors:
      - name: multimodal_extractor
        version: v1
    # Daily spend budget, in dollars of what you are charged (1,000 credits a dollar).
    # New batches pause once the namespace has spent this much today; queries are not capped.
    # Raise it later on the namespace: PATCH /v1/namespaces/<id> {"spend_budget": {"daily_usd": N}}.
    budget:
      daily_usd: 2

# Data sources. A storage connection carries credentials, so it is created in Studio
# (or POST /v1/organizations/storage-connections) and synced into the bucket named here.
#   samples: s3, continuous, your samples with your model's predictions, in your account -> bucket samples
buckets:
  - name: samples
    namespace: ai-data-curation
    description: "Meant to be fed by samples (s3, continuous). No source is connected yet: applying this manifest creates the bucket only. Connect the source to this bucket in Studio (Syncs) to start the feed."
    schema:
      properties:
        image:
          type: image
          required: true
        label:
          type: string
        prediction:
          type: string
        confidence:
          type: number
        correct:
          type: boolean
        error_category:
          type: string
        model_version:
          type: string

# Connect your own storage. Create the two secrets, uncomment, and apply again;
# apply live-tests the connection, so it must have real credentials to succeed.
# Until then the buckets above accept direct uploads.
# storage_connections:
#   - name: samples-connection
#     provider: s3
#     description: "Read-only access to the s3 location holding your samples with your model's predictions, in your account."
#     config:
#       region: us-east-1
#       credentials:
#         type: access_key
#         access_key_id: ${{ secrets.AWS_ACCESS_KEY_ID }}
#         secret_access_key: ${{ secrets.AWS_SECRET_ACCESS_KEY }}

# bucket_syncs:
#   - name: samples-sync
#     bucket: samples
#     connection: samples-connection
#     source_path: "samples/"
#     sync_mode: continuous
#     polling_interval_seconds: 300
#     skip_duplicates: true
#     file_filters:
#       include_patterns: ["*.jpg", "*.jpeg", "*.png", "*.webp"]
#     schema_mapping:
#       mappings:
#         image:
#           target_type: blob
#           source: {type: file}
#           blob_type: image

collections:
  - name: samples
    namespace: ai-data-curation
    description: "multimodal_extractor@v1 over bucket samples. Feeds confident-miss-monitor, confident-miss-indexed, failure-discovery, similar-to-failure, hard-examples, curate."
    source:
      type: bucket
      bucket: samples
    feature_extractor:
      name: multimodal_extractor
      version: v1
      input_mappings:
        image: image
      field_passthrough:
        - source_path: label
        - source_path: prediction
        - source_path: confidence
        - source_path: correct
        - source_path: error_category
        - source_path: model_version
    alert_applications:
      - alert: confident-miss-indexed
        input_mappings:
          - input_key: document_id
            source: {source_type: document_field, path: _internal.document_id}
    enabled: true
retrievers:
  - name: failure-discovery
    namespace: ai-data-curation
    description: "Describe a failure in words and get back every sample that looks like it, labeled or not, so one known miss turns into the set of samples like it."
    collections:
      - samples
    input_schema:
      query:
        type: text
        required: true
        description: "What to look for; searched across every index below"
    stages:
      - stage_name: search
        stage_id: feature_search
        parameters:
          searches:
            - feature_uri: "mixpeek://multimodal_extractor@v1/vertex_multimodal_embedding"
              query:
                input_mode: text
                value: "{{INPUT.query}}"
              top_k: 50
          fusion: rrf
          final_top_k: 50
    tags:
      - template:ai-data-curation
  - name: similar-to-failure
    namespace: ai-data-curation
    description: "Pass the URL of an image the model got wrong and get back the samples closest to it."
    collections:
      - samples
    input_schema:
      query:
        type: text
        required: true
        description: "URL of the image or frame to match; encoded by the index below and compared against it"
    stages:
      - stage_name: search
        stage_id: feature_search
        parameters:
          searches:
            - feature_uri: "mixpeek://multimodal_extractor@v1/vertex_multimodal_embedding"
              query:
                input_mode: content
                value: "{{INPUT.query}}"
              top_k: 50
          fusion: rrf
          final_top_k: 50
    tags:
      - template:ai-data-curation
  - name: hard-examples
    namespace: ai-data-curation
    description: "Every sample the model got wrong, most confident first."
    collections:
      - samples
    input_schema:
      limit:
        type: text
        required: false
        description: "Optional cap on documents grouped per run"
    stages:
      - stage_name: verdict_filter
        config:
          stage_id: attribute_filter
          parameters:
            conditions:
              AND:
                - field: correct
                  operator: eq
                  value: false
      - stage_name: most_confident_first
        stage_id: sort_attribute
        parameters:
          field: "confidence"
          direction: "desc"
    tags:
      - template:ai-data-curation
  - name: curate
    namespace: ai-data-curation
    description: "Search for what a dataset should cover, then keep a diverse, balanced pick: near-duplicates dropped and every label represented."
    collections:
      - samples
    input_schema:
      query:
        type: text
        required: true
        description: "What to look for; searched across every index below"
    stages:
      - stage_name: search
        stage_id: feature_search
        parameters:
          searches:
            - feature_uri: "mixpeek://multimodal_extractor@v1/vertex_multimodal_embedding"
              query:
                input_mode: text
                value: "{{INPUT.query}}"
              top_k: 200
          fusion: rrf
          final_top_k: 200
      - stage_name: drop_near_duplicates
        stage_id: mmr
        parameters:
          lambda: 0.5
          top_k: 100
          diversity_feature_uri: "mixpeek://multimodal_extractor@v1/vertex_multimodal_embedding"
      - stage_name: balance_labels
        stage_id: sample
        parameters:
          strategy: "stratified"
          stratify_by: "label"
          count: 12
          min_per_stratum: 4
          seed: 7
    tags:
      - template:ai-data-curation
  - name: confident-miss-monitor
    namespace: ai-data-curation
    description: "The alert's check: is the sample just written one the model got wrong with confidence 0.8 or higher. The run is scoped to that one sample and reads its fields only, so it calls no model. Materialises into confident-miss-indexed."
    collections:
      - samples
    input_schema:
      document_id:
        type: text
        required: true
        description: "The written document this run is scoped to, supplied by the alert attachment"
    stages:
      - stage_name: verdict_filter
        config:
          stage_id: attribute_filter
          parameters:
            conditions:
              AND:
                - field: _internal.document_id
                  operator: eq
                  value: "{{INPUT.document_id}}"
                - field: correct
                  operator: eq
                  value: false
                - field: confidence
                  operator: gte
                  value: 0.8
    tags:
      - template:ai-data-curation
alerts:
  - name: confident-miss-indexed
    namespace: ai-data-curation
    description: "Emails the org notifications address (Settings -> Notifications; unset means opted out) when a newly indexed sample is one the model got wrong with confidence 0.8 or higher."
    source: retriever
    retriever: confident-miss-monitor
    trigger_on: results
    notification_config:
      channels:
        - channel_type: email
      include_matches: true
      include_scores: true
    enabled: false

# The curation sample set: 20 daytime and 20 night street photos (CC0, from
# Wikimedia Commons), each with the label it truly has and an illustrative
# prediction from a day-or-night scene model. The model gets 16 wrong, 14 of
# them at night, so the failures share a condition the retrievers can find.
# The blobs are the Wikimedia Commons copies of the same photos as
# samples/curation/, because the API serving mixpeek.com does not accept that
# sample set yet. Switch back to the sample keys once it does.
seed:
  - bucket: samples
    max_objects: 40
    objects:
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/9/9d/Steam_in_new_york_street_%28Unsplash%29.jpg/1920px-Steam_in_new_york_street_%28Unsplash%29.jpg"}, label: day, prediction: day, confidence: 0.97, correct: true, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/2/2b/Doorman_on_Leadenhall_Street_%28Unsplash%29.jpg/1920px-Doorman_on_Leadenhall_Street_%28Unsplash%29.jpg"}, label: day, prediction: day, confidence: 0.95, correct: true, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/7/77/Muscle_cars_at_Rundle_Street_%28Unsplash%29.jpg/1920px-Muscle_cars_at_Rundle_Street_%28Unsplash%29.jpg"}, label: day, prediction: day, confidence: 0.93, correct: true, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/d/dc/Driving_outside_Flinders_Street_Railway_Station_%28Unsplash%29.jpg/1920px-Driving_outside_Flinders_Street_Railway_Station_%28Unsplash%29.jpg"}, label: day, prediction: day, confidence: 0.91, correct: true, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/2/2e/First_Street_%28Unsplash%29.jpg/1920px-First_Street_%28Unsplash%29.jpg"}, label: day, prediction: day, confidence: 0.89, correct: true, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/d/d0/Neighborhood_street_%28Unsplash%29.jpg/1920px-Neighborhood_street_%28Unsplash%29.jpg"}, label: day, prediction: day, confidence: 0.97, correct: true, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/d/d4/Street_View_urban_street_%28Unsplash%29.jpg/1920px-Street_View_urban_street_%28Unsplash%29.jpg"}, label: day, prediction: day, confidence: 0.95, correct: true, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/9/9c/Street_%28Unsplash%29.jpg/1920px-Street_%28Unsplash%29.jpg"}, label: day, prediction: day, confidence: 0.93, correct: true, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/3/30/Street_Curve_%28Unsplash%29.jpg/1920px-Street_Curve_%28Unsplash%29.jpg"}, label: day, prediction: day, confidence: 0.91, correct: true, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/0/06/Bleak_city_street_%28Unsplash%29.jpg/1920px-Bleak_city_street_%28Unsplash%29.jpg"}, label: day, prediction: day, confidence: 0.89, correct: true, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/9/93/Shadowed_street_London_%28Unsplash%29.jpg/1920px-Shadowed_street_London_%28Unsplash%29.jpg"}, label: day, prediction: night, confidence: 0.71, correct: false, error_category: deep_shadow, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/7/78/Street_corner_Japan_%28Unsplash%29.jpg/1920px-Street_corner_Japan_%28Unsplash%29.jpg"}, label: day, prediction: day, confidence: 0.95, correct: true, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/1/17/Crossing_The_Street_%28Unsplash%29.jpg/1920px-Crossing_The_Street_%28Unsplash%29.jpg"}, label: day, prediction: day, confidence: 0.93, correct: true, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/7/7f/People_crossing_street_%28Unsplash%29.jpg/1920px-People_crossing_street_%28Unsplash%29.jpg"}, label: day, prediction: day, confidence: 0.91, correct: true, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/2/22/Steep_city_street_%28Unsplash%29.jpg/1920px-Steep_city_street_%28Unsplash%29.jpg"}, label: day, prediction: day, confidence: 0.89, correct: true, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/7/79/London_street_in_the_rain_%28Unsplash%29.jpg/1920px-London_street_in_the_rain_%28Unsplash%29.jpg"}, label: day, prediction: night, confidence: 0.84, correct: false, error_category: overcast, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/b/bc/Cobblestone_street_%28Unsplash%29.jpg/1920px-Cobblestone_street_%28Unsplash%29.jpg"}, label: day, prediction: day, confidence: 0.95, correct: true, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/d/dd/Aerial_view_of_Smolenskaya_Street%2C_Moscow_%28Unsplash%29.jpg/1920px-Aerial_view_of_Smolenskaya_Street%2C_Moscow_%28Unsplash%29.jpg"}, label: day, prediction: day, confidence: 0.93, correct: true, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/2/2f/New_York_Street_Fashion_%28Unsplash%29.jpg/1920px-New_York_Street_Fashion_%28Unsplash%29.jpg"}, label: day, prediction: day, confidence: 0.91, correct: true, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/b/b0/Busy_crossroads_at_daytime_in_Budapest_%28Unsplash%29.jpg/1920px-Busy_crossroads_at_daytime_in_Budapest_%28Unsplash%29.jpg"}, label: day, prediction: day, confidence: 0.89, correct: true, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/1/13/Toronto%2C_Harbour_Street_at_Night_in_2017_-_Sean_Pollock_2017_%28Unsplash%29.jpg/1920px-Toronto%2C_Harbour_Street_at_Night_in_2017_-_Sean_Pollock_2017_%28Unsplash%29.jpg"}, label: night, prediction: day, confidence: 0.52, correct: false, error_category: low_light, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/5/5e/Hong_Kong_night_%28Unsplash%29.jpg/1920px-Hong_Kong_night_%28Unsplash%29.jpg"}, label: night, prediction: night, confidence: 0.87, correct: true, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/0/04/Cityscape_and_traffic_light_trails_%28Unsplash%29.jpg/1920px-Cityscape_and_traffic_light_trails_%28Unsplash%29.jpg"}, label: night, prediction: day, confidence: 0.56, correct: false, error_category: low_light, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/1/12/Flatiron_at_night_%28Unsplash%29.jpg/1920px-Flatiron_at_night_%28Unsplash%29.jpg"}, label: night, prediction: night, confidence: 0.81, correct: true, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/a/ad/Speed_by_night_%28Unsplash%29.jpg/1920px-Speed_by_night_%28Unsplash%29.jpg"}, label: night, prediction: day, confidence: 0.6, correct: false, error_category: low_light, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/7/7f/Man_on_a_bicycle_at_night_%28Unsplash%29.jpg/1920px-Man_on_a_bicycle_at_night_%28Unsplash%29.jpg"}, label: night, prediction: day, confidence: 0.64, correct: false, error_category: low_light, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/2/2d/Inside_a_car_at_night-time_in_Williamsburg_%28Unsplash%29.jpg/1920px-Inside_a_car_at_night-time_in_Williamsburg_%28Unsplash%29.jpg"}, label: night, prediction: day, confidence: 0.68, correct: false, error_category: low_light, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/5/5e/Downtown_Los_Angeles_at_night_%28Unsplash%29.jpg/1920px-Downtown_Los_Angeles_at_night_%28Unsplash%29.jpg"}, label: night, prediction: night, confidence: 0.81, correct: true, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/0/0c/Driving_through_a_bridge_at_night_%28Unsplash%29.jpg/1920px-Driving_through_a_bridge_at_night_%28Unsplash%29.jpg"}, label: night, prediction: day, confidence: 0.72, correct: false, error_category: low_light, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/5/55/Car_light_trails_at_night_%28Unsplash%29.jpg/1920px-Car_light_trails_at_night_%28Unsplash%29.jpg"}, label: night, prediction: day, confidence: 0.76, correct: false, error_category: low_light, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/0/0a/Dim_urban_street_%28Unsplash%29.jpg/1920px-Dim_urban_street_%28Unsplash%29.jpg"}, label: night, prediction: day, confidence: 0.52, correct: false, error_category: low_light, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/a/a2/Boston_firetruck_parked_on_a_street_at_night_%28Unsplash%29.jpg/1920px-Boston_firetruck_parked_on_a_street_at_night_%28Unsplash%29.jpg"}, label: night, prediction: day, confidence: 0.56, correct: false, error_category: low_light, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/2/29/Cobblestone_street_at_night_%28Unsplash%29.jpg/1920px-Cobblestone_street_at_night_%28Unsplash%29.jpg"}, label: night, prediction: day, confidence: 0.6, correct: false, error_category: low_light, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/9/97/Colorful_urban_traffic_at_night_%28Unsplash%29.jpg/1920px-Colorful_urban_traffic_at_night_%28Unsplash%29.jpg"}, label: night, prediction: night, confidence: 0.87, correct: true, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/e/e8/New_York_city_center_street_at_night-time_%28Unsplash%29.jpg/1920px-New_York_city_center_street_at_night-time_%28Unsplash%29.jpg"}, label: night, prediction: night, confidence: 0.84, correct: true, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/0/0d/On_an_empty_road_at_night_%28Unsplash%29.jpg/1920px-On_an_empty_road_at_night_%28Unsplash%29.jpg"}, label: night, prediction: day, confidence: 0.64, correct: false, error_category: low_light, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/9/9c/Highway_intersection_at_night-time_%28Unsplash%29.jpg/1920px-Highway_intersection_at_night-time_%28Unsplash%29.jpg"}, label: night, prediction: day, confidence: 0.68, correct: false, error_category: low_light, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/0/09/Jette_highway_traffic_at_night_%28Unsplash%29.jpg/1920px-Jette_highway_traffic_at_night_%28Unsplash%29.jpg"}, label: night, prediction: day, confidence: 0.72, correct: false, error_category: low_light, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/3/32/Neon_streets_%28Unsplash%29.jpg/1920px-Neon_streets_%28Unsplash%29.jpg"}, label: night, prediction: night, confidence: 0.84, correct: true, model_version: scene-lighting-v1}
      - {blobs: {image: "https://thumb.wikimedia.org/wikipedia/commons/thumb/f/fe/Chicago_nighttime_%28Unsplash%29.jpg/1920px-Chicago_nighttime_%28Unsplash%29.jpg"}, label: night, prediction: day, confidence: 0.76, correct: false, error_category: low_light, model_version: scene-lighting-v1}
# Measured on production 2026-10-29: the seed and these four queries cost
# 880 credits ($0.88), nearly all of it the 40 image embeddings.
acceptance:
  max_cost_usd: 1.25
  steps:
    - name: samples-indexed
      kind: documents
      collection: samples
      expect: {min_documents: 40}
    - name: failure-discovery-finds-night
      kind: query
      retriever: failure-discovery
      inputs: {query: a dark city street at night}
      expect: {top_field: label, top_equals: night}
    - name: hard-examples-ranks-the-most-confident-miss
      kind: query
      retriever: hard-examples
      expect: {top_field: error_category, top_equals: overcast}
    - name: curate-returns-a-stratified-pick
      kind: query
      retriever: curate
      inputs: {query: a city street}
      expect: {min_results: 8}
Read from the manifest, so a part it ships commented out never shows as ready.
What each part needs
- samples
- Deploys and processes documents as they arrive.
- failure-discovery
- Deploys and answers queries once its collections hold documents.
- similar-to-failure
- Deploys and answers queries once its collections hold documents.
- hard-examples
- Deploys and answers queries once its collections hold documents.
- curate
- Deploys and answers queries once its collections hold documents.
- confident-miss-monitor
- Deploys and answers queries once its collections hold documents.
- attribute_filter
- The one-click manifest includes this stage.
- sort_attribute
- The one-click manifest includes this stage.
- mmr
- The one-click manifest includes this stage.
- sample
- The one-click manifest includes this stage.
- samples
- Create the s3 credentials as manifest secrets, then uncomment the sync. It ships commented out because apply tests a connection as it creates it.
| Component | Role | Source | Today |
|---|---|---|---|
| multimodal_extractor@v1 | Embeds each image into the space a text query and an image query shareRuns on CPU through the Vertex API, so the template does not wait on GPU capacity. | Built in | Deploys ready |
| attribute_filter | Keeps the samples your data marks as wrong (correct = false) | Built in | Deploys ready |
| sort_attribute | Ranks them by your model's confidence, highest first | Built in | Deploys ready |
| mmr | Drops near-duplicates by trading relevance for distance on the image vector | Built in | Deploys ready |
| sample | Takes a stratified pick across labels so one condition cannot fill the set | Built in | Deploys ready |
Apply the manifest and the namespace comes up with one collection and four retrievers, with a daily budget of 2 USD.
The same manifest applies against a customer-hosted deployment when the samples cannot leave your environment.
- Permissions
- A key with namespace create and collection create. The storage connection is a separate grant and the manifest ships it commented out, because apply live-tests a connection and would roll the whole namespace back on a bad credential.
- Footprint
- One collection, one document per sample, with one multimodal vector each. No GPU is needed.
The acceptance checks from the proof run: 40 samples indexed; failure-discovery ranks a night sample first for "a dark city street at night"; hard-examples ranks the overcast miss first; curate returns at least 8 for "a city street"; cost under 1.25 USD.
| Category | Rule |
|---|---|
| Failure discovery | A described failure returns samples with that failure at the top. On the seed set the top 5 for night scenes were all night. |
| Hard examples | Every row is a wrong prediction and the order is by confidence, descending. Checkable without ground truth beyond what you sent. |
| Curated pick | Every label meets its minimum (4) and the pick holds no near-duplicates of each other. |
On the proof run, 40 images indexed in about 4 minutes after apply; queries answered in 0.7 to 1.4 s warm and 23.9 s on the first, cold call.
Does Mixpeek label the data or train the model?+
No. Mixpeek finds and selects. Labeling, training and model evaluation stay in your own tools, and the selection reaches them as an export they can pin.
Does it tell me which predictions are wrong?+
No. You send correct and error_category with each sample, from your own evaluation. hard-examples filters and ranks on those fields.
Can it group failures into clusters?+
Not in this version. A cluster over the samples, writing a cluster label onto every document, is the next phase, and it needs only cluster and retriever configuration.
Does it work on video?+
This version is images only. The extractor already takes video and text as separate inputs, so video is a schema change rather than a new pipeline.
How is this different from the video moderation template?+
Video moderation screens footage against a policy and records why each segment was flagged. This template picks the examples a model needs to learn from.